Introduction
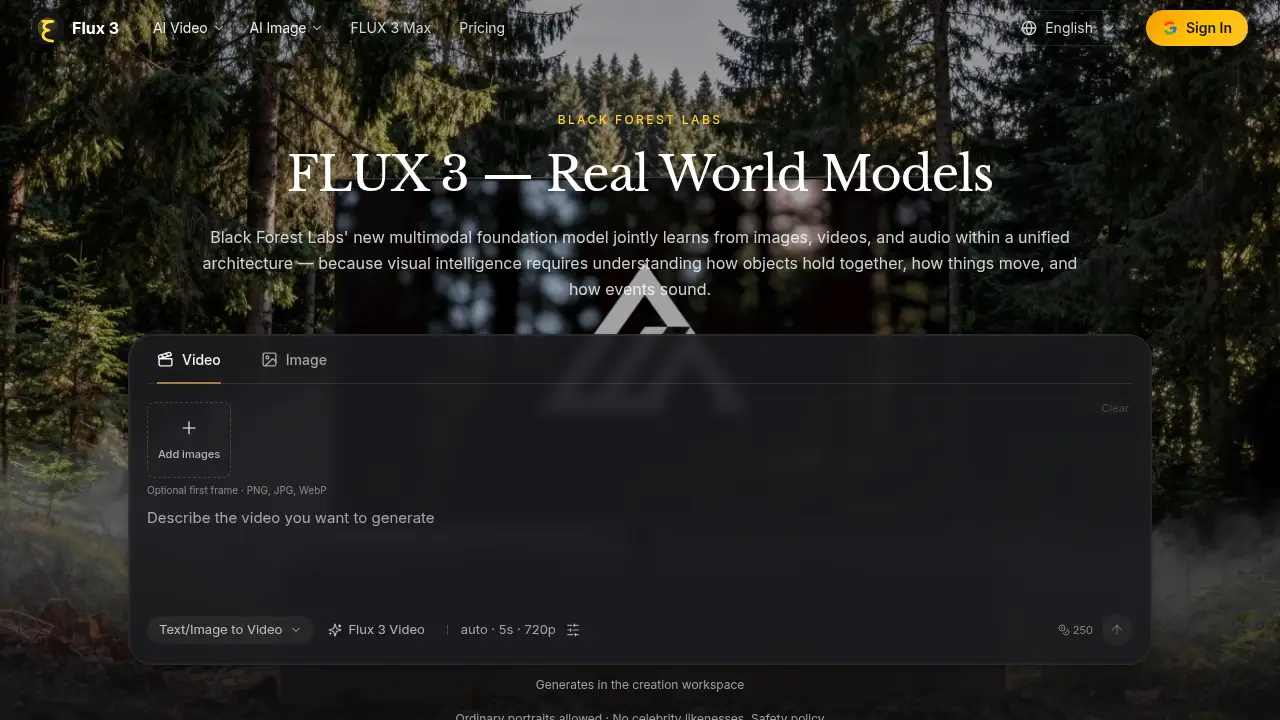
Flux 3 is a multimodal foundation model from Black Forest Labs that learns from images, videos, and audio inside one unified architecture. Instead of converting one media type at a time, Flux 3 aims to understand how objects hold together, how things move, and how events sound — bringing video generation, image editing, and native audio into a single creative system.
What is Flux 3?
Flux 3 is Black Forest Labs' new multimodal foundation model, built on a technique the company calls Self-Flow, which aligns multimodal generation and understanding within the same architecture and scales it across video, images, and audio at once. The core problem it addresses is fragmentation: most creative tools treat video, stills, and sound as separate jobs handled by separate models. Flux 3 treats them as one world to be understood.
That matters because visual intelligence depends on context. A model that knows how a glass shatters also knows how it should sound and how the pieces should move across frames. Flux 3 is released in phases through early access, with video generation available first and further capabilities rolling out over time.
The model is designed for creators, marketers, designers, and robotics teams who want an intelligent creative partner rather than a single-modality converter. In short, Flux 3 is a multimodal AI system that tries to model the real world, not just render it.
Key Features of Flux 3
Video Generation with Native Audio
Generate text-to-video clips, animate a starting image, transfer references between videos, and continue existing footage — all with synchronized native audio up to roughly 20 seconds. Keyframe-to-video control gives creators tighter direction over motion and pacing.
Multilingual Dialogue and Sound Design
Capture human facial expressions, tie sounds to physical events, and produce multilingual dialogue inside one sequence. Flux 3 combines these abilities into flows that can last several minutes rather than a few disconnected seconds.
Agentic Multi-Shot Chaining
Chain individual clips into longer, multi-shot sequences with visual references that help characters stay consistent across scenes. This makes Flux 3 video generation more useful for narrative work than one-off prompt-to-clip tools.
Image Synthesis and Editing
Synthesize and edit images across a wide range of styles, aspect ratios, and resolutions. Complex prompt adherence and high-accuracy text rendering in multiple languages make image editing practical for real design tasks.
Style Diversity and Typography
Move between candid camcorder footage, animation, and cinematic looks within the same model. Flux 3 also handles typography and animated design work, which is often where generative video tools fall short.
Action Prediction
Flux 3 includes native action prediction, and specialized fine-tuned models such as FLUX-mimic build on the pretrained video backbone as a dynamics-aware foundation. This is the bridge between generative media and physical AI.
Early Benchmark Performance
In preliminary 720p text-to-video evaluations, Flux 3 was preferred over several leading models in head-to-head comparisons, with further improvements expected during early access.
Use Cases for Flux 3
Creative and Social Video Production
Produce short-form clips with native audio, typography, and consistent styling for social channels. Creators can iterate quickly in the Flux 3 creation workspace without switching between separate video and audio tools.
Marketing and Ad Campaigns
Build multi-shot promos where characters and products stay visually consistent across scenes. Marketers can test concepts with Flux 3 multimodal AI before committing to a full production budget.
Design and Image Editing
Generate and refine stills in many aspect ratios, then render accurate multilingual text directly in the image. Designers get a single workflow instead of juggling image editing and video generation apps.
Robotics and Physical AI Research
Use action prediction and a dynamics-aware video backbone to explore simulation and computer-use scenarios. Flux 3 supports teams working on embodied AI, where understanding motion matters as much as rendering it.
Storytelling and Multi-Shot Narratives
Chain clips into extended sequences with reference-guided consistency. Flux 3 helps storytellers assemble scenes that feel connected rather than randomly generated.
How to Use Flux 3
- Visit the Flux 3 website and open the creation workspace through early access.
- Choose your mode — text-to-video, image-to-video, or video-to-video reference transfer.
- Optionally upload a first frame as a PNG, JPG, or WebP file to guide the opening shot.
- Write a clear prompt describing the subject, motion, style, and any dialogue or sound you want.
- Generate the clip, review the result, then chain or refine shots as needed. Keep prompts and content within the platform's safety and acceptable-use policy.
Target Audience for Flux 3
- Video creators and social media storytellers
- Marketers and brand campaign teams
- Designers working across image and motion
- Filmmakers and animators prototyping scenes
- Robotics and physical AI research teams
- Developers exploring multimodal AI systems
Is Flux 3 Free?
Flux 3 is currently rolling out in phases through early access, and public pricing details are limited. The model's pricing page is the most reliable place to confirm current plans, credits, and limits.
| Plan | Price | Features |
|---|---|---|
| Early access | Varies | Access to phased Flux 3 capabilities, including video generation |
| Paid tiers | See official pricing page | Higher generation volume and expanded feature access |
Because generation appears to consume credits in the creation workspace, users should check the official pricing page at flux3.dev/pricing before planning larger projects.
Flux 3's Pros and Cons
| Aspect | Pros | Cons |
|---|---|---|
| Capabilities | Unified video, image, audio, and action prediction in one model | Not all capabilities available at launch |
| Audio | Native synchronized audio and multilingual dialogue | Clips are limited to around 20 seconds per generation |
| Consistency | Multi-shot chaining with visual references keeps characters stable | Longer narratives still require manual chaining |
| Access | Phased early access invites feedback and safety testing | Pricing and limits are not fully published |
| Style range | Broad coverage from camcorder footage to cinematic looks | Benchmark results are preliminary |
Frequently Asked Questions about Flux 3
What is Flux 3?
Flux 3 is a multimodal foundation model from Black Forest Labs that jointly learns from images, videos, and audio. It powers video generation, image editing, and action prediction from the same underlying architecture.
Does Flux 3 generate audio as well as video?
Yes. Flux 3 video generation includes synchronized native audio, along with multilingual dialogue and sound design tied to physical events in the scene.
How long can Flux 3 clips be?
Individual video generations run up to about 20 seconds, and multi-shot chaining can be used to build longer sequences with consistent characters.
Is Flux 3 available to everyone?
Flux 3 is being released in phases through early access, starting with video generation. Additional capabilities are expected as feedback and safety testing continue.
Can Flux 3 be used for image editing?
Yes. Flux 3 supports image synthesis and editing across styles, aspect ratios, and resolutions, with improved prompt adherence and multilingual text rendering.
What makes Flux 3 different from single-modality tools?
Flux 3 multimodal AI shares world understanding across video, image, and action rather than treating each format separately, which helps with consistency, motion, and sound.
Flux 3 Tags
Flux 3, Flux 3 multimodal model, Black Forest Labs, multimodal AI, Flux 3 video generation, native audio AI video, text-to-video model, AI image editing, multi-shot video chaining, action prediction AI, FLUX-mimic, generative video with audio